Practice Area
Data Observability
Monitor data health, freshness, drift, and pipelines 24/7 so that issues are detected early and resolved before they affect business decisions.
Get to know us Let's talk
Overview
From Data Checks to
From Data Checks to
Data Trust
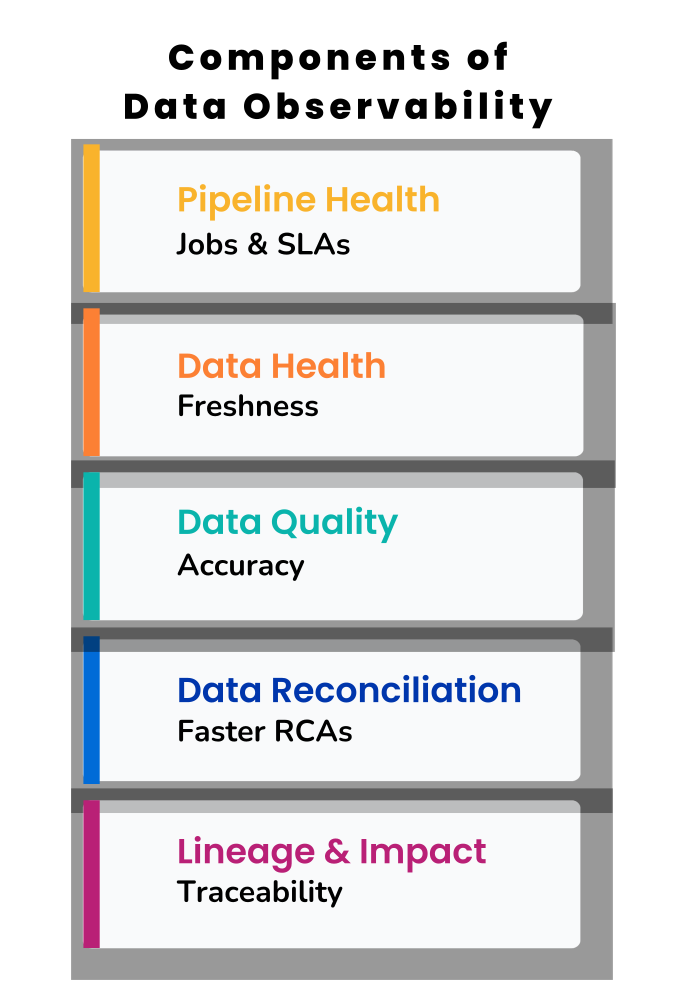
Modern data platforms operate across distributed pipelines, cloud warehouses, lakehouses, and analytics products, making it difficult to know when data has become unreliable. Data Observability extends traditional data quality by combining pipeline health, metadata, lineage, freshness, volume, schema, and data quality signals with continuous monitoring and actionable alerts.
The objective is not simply to detect failed checks, but to understand how changes in upstream processes or data patterns can impact downstream reporting, analytics, and AI. Statistical monitoring can establish normal operating ranges and surface unexpected variation or drift before it becomes a business issue. This creates a measurable, operational layer of trust across the data lifecycle.
Our Expertise
Business Outcomes Through
Trusted Data
We view Data Observability as an operational capability that brings together data quality, pipeline monitoring, metadata, lineage, and issue management. Our approach starts with the data products and business outcomes that matter most, then defines the signals and thresholds needed to monitor their reliability.
We combine rule-based validation with profiling and statistical techniques to detect quality failures, freshness issues, volume anomalies, schema changes, and changes in data distribution. Observability is designed into the platform rather than added as a standalone dashboard, with alerts, ownership, root-cause analysis, and remediation workflows connected to operational teams.
Our Point of View
Building Continuous Data Trust
Business-Critical Monitoring
Quality and Pipeline Signals
Metadata and Lineage Context
Statistical Drift Detection
Root-Cause and Issue Management
Build Continuous Trust
How We Help
Where to Start
We help organizations establish and scale Data Observability across modern data platforms, from assessment and framework design through implementation and managed monitoring.
Our Experience
Related Case Studies
Explore real-world impact stories of how we help organizations overcome complex challenges and scale for the future.
Challenge
The organization had multiple data pipelines and source systems that made it difficult to identify failures and quality degradation before downstream consumption. Traditional checks focused on individual rules built for every dataset and did not provide sufficient visibility into metadata, pipeline behavior, or changing data distributions.
Solution
We designed a Databricks-based Data Observability Framework covering pipeline health, technical metadata, lineage, and data quality rules across critical data flows. We implemented reusable metadata- and data-level checks, with historical profiling and statistical methods to detect volume, distribution, and data drift, and established centralized monitoring, alerting, issue triage, and root-cause analysis using pipeline and lineage context.
Outcome
The program enabled earlier detection of pipeline and data quality issues before they affected downstream analytics, improved visibility into data behavior and changes across critical pharmaceutical data products, and created a repeatable observability pattern that could be extended across additional pipelines and domains.
Integrated Reporting
Challenge
The organization had BI reporting that depended on data from multiple operational and investment-related sources, creating recurring quality and reconciliation issues. Data teams needed consistent monitoring of completeness, validity, freshness, and business-rule conformance without relying on manual reporting checks.
Solution
We built a Snowflake-based data quality monitoring framework for critical BI datasets and reporting data products. Blue Altair implemented reusable quality rules and profiling checks for completeness, validity, consistency, referential integrity, freshness, and business-rule conformance, and established quality scorecards, trend monitoring, thresholds, and issue reporting so data teams could identify and prioritize defects affecting BI outputs.
Outcome
The program improved confidence in data feeding management and investment reporting, reduced dependence on manual validation and reconciliation activities, and created a scalable quality monitoring foundation that could be extended to additional BI data products.
What Brought You Here?
Data Quality Issues Detected
Understand how our jumpstart Data Observability Framework can accelerate data quality issue identification.
→
Data Drift and Anomaly Detection
Explore a solution that detects data drift for AI models through scheduled monitoring.
→
BI Reporting Data Validation
See how our expertise leads to faster data issue identification and remediation.
→
Data Observability Framework
Explore advisory, customized, and platform enablement expertise
→